
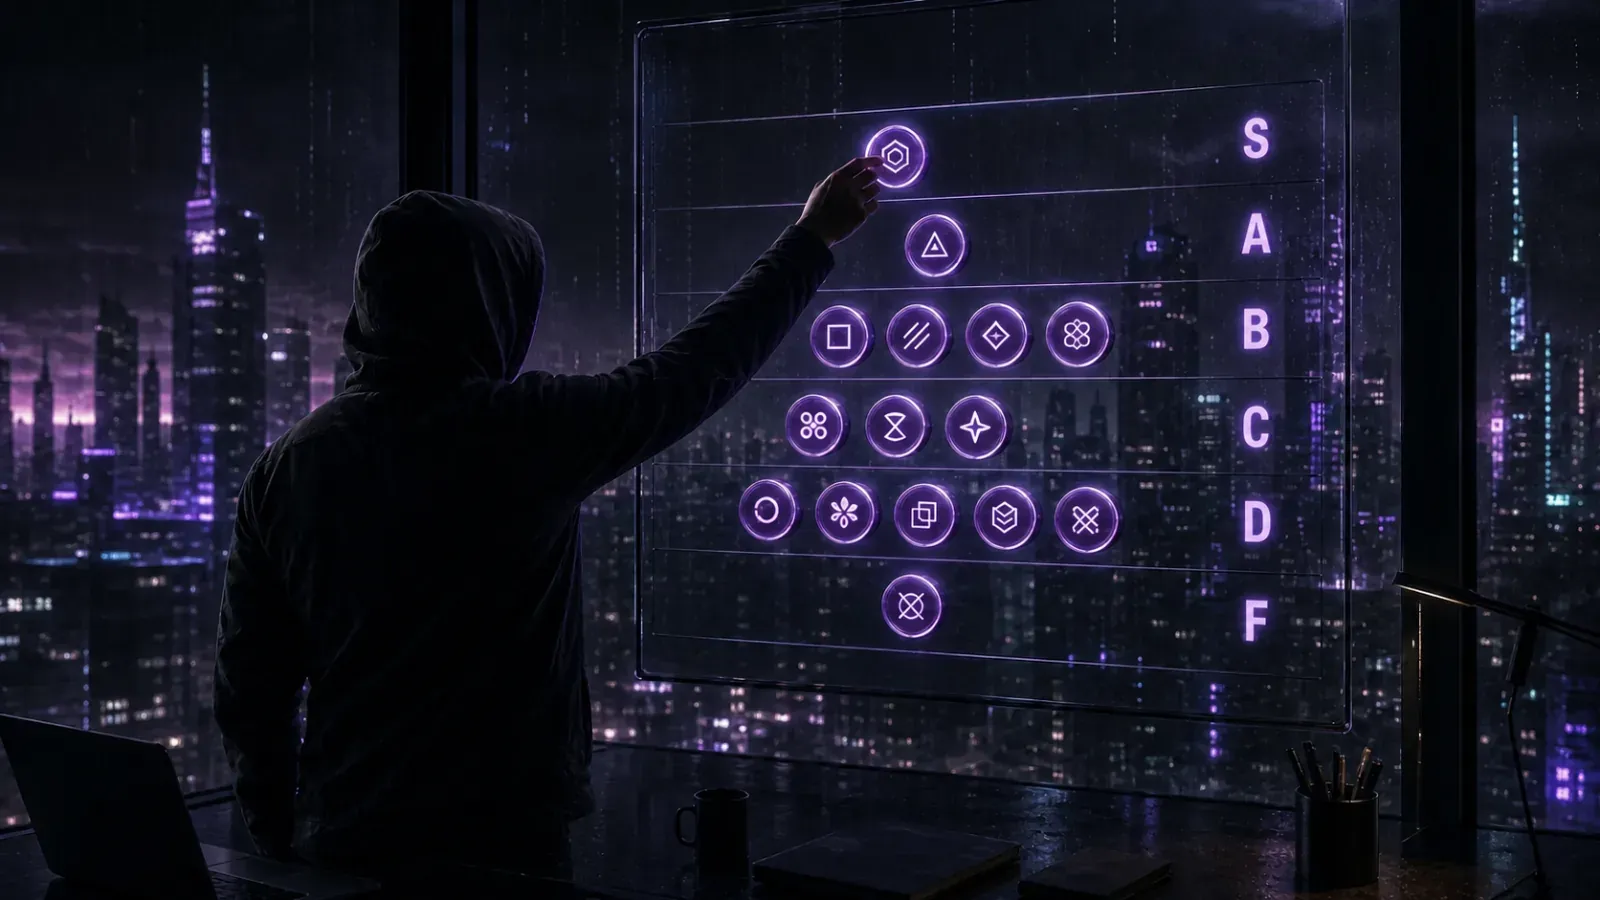
October’s AI Tier List is up to nineteen models from September’s seventeen. Eight of last month’s models have newer versions in their spots. MiMo-V2.6-Pro and Qwen3.8-Max are the two new names.
Don’t compare the scores to last month’s: Artificial Analysis changed its Intelligence Index four times in September, so every score changed. I’m also giving Opus 5.5 S+ to itself partly for how much you can use it on a Claude subscription. That’s the one place I’m letting the monthly plan help decide the rank, and the API price alone doesn’t do it justice.
AI Model Tier List
Last updated: October 8, 2026Hover a model, or tab to it, for the one-line reason it ranks where it does.- S+Daily driver
- Opus 5.5$8.00/M
- AReach for it
- Sonnet 5.5$4.00/M
- GPT-6 Astra$20.00/M
- GPT-6.1 Sol$4.00/M
- Muse Spark 1.3$2.00/M
- MiMo-V2.6-Pro$0.54/M
- glm-5.3$2.15/M
- BGood, not first
- glm-5.3-flash$0.24/M
- GPT-6 Luna$0.20/M
- deepseek v4.1 flash$0.53/M
- Gemini 3.8 Flash$1.50/M
- Grok 4.7$3.00/M
- CSituational
- Fable 5.1$20.00/M
- kimi k3$6.00/M
- Qwen3.8-Max$3.00/M
- DNiche at best
- Composer 2.5$1.00/M
- deepseek v4 pro$1.98/M
- FSkip it
- gpt-5.6-terra$4.50/M
- Gemini 3.1 Pro Preview$4.50/M
Every price is the standard published rate from the vendor's own pricing page, blended at three parts input to one part output. Batch, cached and off-peak rates are excluded. All nineteen were retrieved October 4, 2026. Eight things on this board aren't what they look like, and the section near the end says which. Opus 5.5's S+ placement also weighs subscription value, which the chip price doesn't show.
S+: The Best Model Got Cheaper
Opus 5.5 stands alone here with the top index score of 58. This is the one row on the board where I also count what a subscription buys, because Claude’s plans offer about five times the API-equivalent allowance per dollar of OpenAI’s equivalent plans on SemiAnalysis’s agentic mix. The score puts it first, and the subscription value puts it in a tier of its own.
Opus 5.5
Anthropic released it on September 22, 2026 at $4 in and $20 out, twenty percent below Opus 5, with cache reads down from $0.50 to $0.20. Artificial Analysis scores it at 58, "the highest score we have measured by several points." Sonnet 5.5 closed that to two points six days later. Fable 5.1, last month's number one, scores 53 and costs two and a half times as much.
The 58 comes with a footnote: it's measured at maximum effort, and the API defaults Opus 5.5 to medium. At high effort it scores 54 for $1.82 a task, which would still earn it S+.
At maximum it costs $5.98 a task, burning about 119,000 output tokens to get there. Opus 5 burned about 73,000.
On Claude Max 20x at $200 a month, SemiAnalysis puts the full monthly Opus 5.5 allowance at $11,726 in API-equivalent value on its agentic mix. On its chat mix, that allowance is worth $9,200 at API rates. ChatGPT Pro 200 costs the same monthly fee but gives GPT-6.1 Sol $2,084 on the agentic mix.
These are full allowances priced at first-party list API rates, not actual usage or savings, and the limits are measured from usage meters rather than published by either lab, so they can change.
Opus 5's reception in r/ClaudeCode was much colder than its benchmark. One active thread describes it as difficult to steer and exhausting to supervise, with users objecting to its long, convoluted answers. That thread is about Opus 5, not 5.5, and it's user reports, not a controlled evaluation. But it's the reputation 5.5 inherits, and nothing in the token count says the habit is gone.
What the Opus 5 thread says: The complaint is less about benchmark quality than communication. Simple answers become long, convoluted explanations, even after requests to be concise.
A: The Row Where The Price Tag Lies
Every model in this row is worth reaching for, but this is where the blended price stops predicting the bill. Astra’s rate is five times Sonnet 5.5’s, and its tasks cost less than half as much. GPT-6.1 Sol moves down here because its subscription allowance falls short of Claude’s.
Sonnet 5.5
Released September 28, 2026 at the same $2 in and $10 out that Sonnet 5 settled on after its price rise was cancelled. It scores 56, second on the index and two points behind Opus 5.5, at half the blended price. On price alone, that's the best deal near the top of the list.
It isn't, and the reason is tokens. Artificial Analysis measured about 193,000 output tokens per task, "the highest token use we have measured." That's about 60 percent more than Opus 5.5 and roughly seven times Astra.
So at $4 blended, a task costs $7.67, more than Fable 5.1 costs at $20. At xhigh effort it drops to 52 and $2.75 a task. That's where I'd run it.
Artificial Analysis says it tested a pre-release build with a structured-outputs bug and will re-run the affected evaluations. The 56 may still move.
It's the more careful of the two new Anthropic models, though. The same evaluation has it hallucinating less than Opus 5.5, 47 percent against 59, while knowing less, 54 percent accuracy against 66.
GPT-6 Astra
OpenAI shipped it on September 3, 2026, the morning after this list first went up, and its president closed the briefing with "Welcome to the AGI era." A month on, it scores 53 on the current index. That's level with Fable 5.1 on the same $20 chip, and three points behind Sonnet 5.5.
The blended price is still the wrong number for it. Astra spends about 27,000 output tokens on a task where Opus 5.5 spends about 119,000, and Artificial Analysis puts its cost at $3.26 a task, against $7.63 for Fable 5.1 and $7.67 for Sonnet 5.5. OpenAI added an Ultrafast mode on September 29 at $60 in and $300 out, six times the standard rate, for when you'd rather pay than wait.
It's also the first model OpenAI has rated Critical for cyber capability under its Preparedness Framework. The system card calls it "our first model to reach the Critical level of cybersecurity capability."
GPT-6.1 Sol
OpenAI shipped GPT-6 Sol on September 22, 2026 and replaced it a week later with GPT-6.1 Sol, at the same $2 in and $10 out. That's half of gpt-5.6-sol's promotional price, for a model that scores 52 where gpt-5.6-sol scores 47. The promo that was the biggest gotcha on last month's list stopped mattering before it expired.
It's six points behind Opus 5.5 at half the blended price. Artificial Analysis measures it at $0.72 a task, about an eighth of what Opus 5.5 spends at maximum effort, and it sits one point below Astra for under a quarter of Astra's cost.
The window is 1.05 million tokens now, though every GPT-6 model still bills the whole request at double input above 272K.
On the API, it's still the cheapest way to get near the top of the board. But OpenAI halved the usage in its $200 plan on September 29 while keeping the price the same. New purchases get the lower limits immediately, while subscribers who bought before the cut keep their old limits until October 29.
On SemiAnalysis's agentic mix, Claude's equivalent plans give about five times the usage allowance priced at API rates for the same monthly fee. That subscription gap is why Sol drops to A.
Muse Spark 1.3
Meta's, released September 2, 2026, the day after last month's prices were checked. I added Astra five days later and still missed this one, which is on me. 1.3 keeps 1.2's $1.25 in and $4.25 out, doubles the window to 1M, and scores 48 where 1.2 now scores 40.
Meta also sells a contributor tier at $0.10 in and $0.20 out, and the catch is in the name: your prompts become training data. It isn't the price on the chip, and for business data I wouldn't go near it.
MiMo-V2.6-Pro
Xiaomi's, released September 22, 2026, with weights on Hugging Face under a plain MIT licence and a price Xiaomi left unchanged from V2.5. It's new to this list and earned the spot on numbers alone: it matches Grok 4.7's 46 for under a fifth of the price.
Artificial Analysis measures it at $0.13 a task. Nothing else above B comes close to that. I haven't run it on client work yet, so this placement is the index talking, not me.
glm-5.3
Z.ai released it on August 18, 2026 and published its weights ten days later. It scores 45, one point ahead of kimi k3 for roughly a third of the price, and Z.ai's docs give it a 1M window, not the 200K I printed last month.
Its licence is more restrictive than the plain MIT terms on glm-5.3-flash. Model-as-a-service providers with more than ten billion dollars in revenue must first pass a Z.ai security review.
Two of these six ship downloadable weights. That’s not a rounding error in a row this close to the top.
B: The Tier That Should Change How You Budget
Four of these five cost less than two dollars per million tokens blended. The fifth is Grok 4.7, which is cheap per token and not cheap to run.
glm-5.3-flash
Still one of the cheapest things here at $0.24, and still MIT. The launch promotion that halved its rate ended on September 9, so the published rate on the chip is the one you pay. It scores 42, exactly what gpt-5.6-terra scores for nineteen times the price.
What keeps it out of the rows above is still the word in its name. Artificial Analysis clocks it at about 53 output tokens a second. That's faster than last month, and still slow enough that anyone waiting on it will notice. Cheap tokens, expensive minutes.
GPT-6 Luna
The cheapest model on the board at $0.20 blended, and the cheapest work too: seven cents a task, as Artificial Analysis measures it. It shipped alongside GPT-6 Sol on September 22, 2026 and scores 38, one point above the gpt-5.6-luna it replaces at less than half the price.
deepseek v4.1 flash
DeepSeek retired v4 flash on September 10, 2026 and pointed the old name at this one, so anyone still calling v4 flash is already paying the new rate. That's $0.30 in and $1.20 out at peak and half that off-peak, for a model that scores 39, three points better than DeepSeek's own Pro. The weights are MIT again.
Gemini 3.8 Flash
Released September 2, 2026, the same day as Muse Spark 1.3, and the other row I missed. It scores 41 at $1.50 blended and edges out the 3.7 Flash it replaces at the same price. Both of its rates double on January 1, 2027.
Grok 4.7
xAI's, released September 21, 2026 at the same $2 in and $6 out as Grok 4.6, and two points better at 46. Last month Grok had the best price-to-score ratio above B. This month Artificial Analysis measures $3.74 a task, more than Astra, because it spends so many tokens getting there. Down a row.
The lesson of this row hasn’t changed. Cheap models aren’t automatically good, but the gap between the cheap ones and the expensive ones has closed enough that the expensive ones have to justify a multiple, not a margin.
C: Good At Something, Priced For Everything
Three models worth paying for if you need what they’re good at.
Fable 5.1
Last month it topped this list at 66. On the current index it scores 53, below both Opus 5.5 and Sonnet 5.5, and it still costs $10 in and $50 out. At maximum effort it finishes a task for $7.63, which would buy you a 58 from Opus 5.5 with change left over.
It stays in C because it's still the most accurate model Artificial Analysis has tested on facts, at 67 percent on their knowledge benchmark. I'd pay for that when the work is long, fact-sensitive and expensive to get wrong.
kimi k3
Moonshot still publishes open weights for a 2.8-trillion-parameter model, which is still a strange sentence to be able to write. It always reasons, which is why its output rate is five times its input. But at $6 blended it scores 44, one point behind glm-5.3 at roughly three times the price.
Moonshot's newer K2.8 Preview only ships inside its Kimi Code subscriptions, so it has no API price to put on a chip.
Qwen3.8-Max
Alibaba's flagship, released August 3, 2026, and new to this list. It scores 45, level with glm-5.3, at $2 in and $6 out. That's a fair blended price, but Artificial Analysis measures $5.41 a task, more than two and a half times glm-5.3.
The weights are downloadable under Alibaba's own licence, but the download is text-only with a 262K window, not the 1M you get from the API.
D: Paying For The Wrong Thing
Two models. One is good at a job this list doesn’t measure, and the other loses to its own cheaper sibling.
Composer 2.5
The cheapest model in this row by some way, which is a strange thing to find in D until you notice it isn't really a general model: Cursor's own launch post says it's built on the same open-source checkpoint as Composer 2, Moonshot's Kimi K2.5.
It's also the one model with no number in the index column below. Artificial Analysis rated it on their coding agent index instead, where it placed third at its May launch. That index is three versions on now, and Composer isn't in the current one, so treat the third place as history. It was measuring a different thing than every other row here anyway.
deepseek v4 pro
Last month it cost exactly three times its Flash sibling and scored one point higher. Then DeepSeek replaced the Flash, and the new one is cheaper and better: $0.30 in and $1.20 out against the Pro's $1.32 and $3.96, and 39 on the index against the Pro's 36.
DeepSeek had planned to redirect the Pro to the new model on September 14 and then reversed that, so it's still for sale. I can't find a reason to buy it.
Ranking the Pro two rows below the Flash was the boldest call on last month’s list. The index now has the Flash ahead outright, which makes it the easiest call on this one.
F: Two Models I Can’t Justify
gpt-5.6-terra
The middle tier of the GPT-5.6 family, made pointless by OpenAI's own replacement. GPT-6.1 Sol scores 52 at $4 blended. Terra scores 42 at $4.50. glm-5.3-flash matches its score for a nineteenth of the price.
Gemini 3.1 Pro Preview
The oldest model here by a distance. It was released on February 19, 2026, it's still labelled Preview, and it still prices identically to gpt-5.6-terra. A model holding its launch price while everything around it gets cheaper is a statement about where its vendor's attention has moved.
It also carries the lowest score on the list, six points below anything else. Every single model above it is cheaper, better, or both. That's what F is for.
A couple gotchas
Eight things on this list aren’t what they look like, and most of them will be wrong in a post written a month from now. The first two change how to read the whole board, so they go first.
The index changed under every row. Artificial Analysis replaced Intelligence Index v4.1.1 with v4.2 on September 4, 2026, then with v4.3 on September 7, and after a v4.3.1 the current version is v4.3.2, from September 19. v4.3 moved Terminal-Bench to version 4.0, added an automation benchmark and raised private held-out sets to 45 percent of the weighting. Every number fell: Fable 5.1 went from 66 to 53. This whole column is v4.3.2 now, read October 4. A score quoted without its version number is not a score.
The blended price is the wrong way to read the top of the board. Last month this was one row, Astra. Now it’s most of the frontier. Models spend wildly different amounts of tokens on the same task: Sonnet 5.5 about 193,000, Opus 5.5 about 119,000, Astra about 27,000. Sonnet costs $4 blended and $7.67 to finish a task. Astra costs $20 blended and $3.26. That’s why the spec sheet has a cost-per-task column this month. The chip says what a token costs. The column says what the work costs.
The scores are best-case settings. Artificial Analysis publishes each model at its best configuration, which usually means maximum effort, and that’s rarely what anybody runs. Opus 5.5 is 58 at max and 54 at high, where a task costs $1.82 instead of $5.98. The API defaults it to medium, where it scores 51, the same as Opus 5 at max. Compare models at the effort you’ll actually use.
Gemini 3.8 Flash’s price is dated. Google’s pricing page gives $0.75 in and $3.75 out through December 31, 2026, then $1.50 and $7.50 starting January 1, 2027. The blended price on the chip doubles on New Year’s Day.
Both DeepSeek prices are peak rates. DeepSeek charges half price outside its peak windows, which are 01:00 to 04:00 and 06:00 to 10:00 UTC on weekdays. If your work can wait for the discount, both chips are twice what you’d pay.
Long prompts cost more almost everywhere. Every GPT-6 and GPT-5.6 model bills the whole request at double input and one and a half times output above 272K input tokens. Grok doubles from 200K. Gemini 3.1 Pro Preview goes to $4 in and $18 out above 200K. If your workload is long documents, the chips on this board are the wrong numbers for you.
One of the top scores isn’t on the board. Gemini 4 Argon scores 53, level with Fable 5.1 and Astra. Google announced it on September 30 and gave it only to trusted cyber defenders in its Fairwind Program. There’s no public API, so there’s no price to rank it on. When it ships, it goes straight onto this board.
Anthropic’s cheapest tier is about to change. The Sonnet 5.5 announcement says Claude Haiku 5.5 “will join the Claude 5.5 family in the coming weeks.” There’s no price or date yet. Haiku 4.5 isn’t on this list, and its successor might change that.
| Model | Input | Output | Blended | Context | Released | Index | Cost/task |
|---|---|---|---|---|---|---|---|
| Opus 5.5 | 4.00 | 20.00 | 8.00 | 1M | Sep 22, 2026 | 58 | 5.98 |
| Sonnet 5.5 | 2.00 | 10.00 | 4.00 | 1M | Sep 28, 2026 | 56 | 7.67 |
| GPT-6 Astra | 10.00 | 50.00 | 20.00 | 1.05M | Sep 3, 2026 | 53 | 3.26 |
| GPT-6.1 Sol | 2.00 | 10.00 | 4.00 | 1.05M | Sep 29, 2026 | 52 | 0.72 |
| Muse Spark 1.3 | 1.25 | 4.25 | 2.00 | 1M | Sep 2, 2026 | 48 | 1.60 |
| MiMo-V2.6-Pro | 0.435 | 0.87 | 0.54 | 1M | Sep 22, 2026 | 46 | 0.13 |
| glm-5.3 | 1.40 | 4.40 | 2.15 | 1M | Aug 18, 2026 | 45 | 2.01 |
| glm-5.3-flash | 0.15 | 0.50 | 0.24 | 1M | Aug 26, 2026 | 42 | 0.25 |
| GPT-6 Luna | 0.10 | 0.50 | 0.20 | 1.05M | Sep 22, 2026 | 38 | 0.07 |
| deepseek v4.1 flash | 0.30 | 1.20 | 0.53 | 1M | Sep 10, 2026 | 39 | 0.27 |
| Gemini 3.8 Flash | 0.75 | 3.75 | 1.50 | 1M | Sep 2, 2026 | 41 | 1.24 |
| Grok 4.7 | 2.00 | 6.00 | 3.00 | 500K | Sep 21, 2026 | 46 | 3.74 |
| Fable 5.1 | 10.00 | 50.00 | 20.00 | 1M | Sep 1, 2026 | 53 | 7.63 |
| kimi k3 | 3.00 | 15.00 | 6.00 | 1M | Jul 27, 2026 | 44 | 2.00 |
| Qwen3.8-Max | 2.00 | 6.00 | 3.00 | 1M | Aug 3, 2026 | 45 | 5.41 |
| Composer 2.5 | 0.50 | 2.50 | 1.00 | 200K | May 18, 2026 | — | — |
| deepseek v4 pro | 1.32 | 3.96 | 1.98 | 1M | Aug 13, 2026 | 36 | 0.67 |
| gpt-5.6-terra | 2.00 | 12.00 | 4.50 | 1.05M | Jul 9, 2026 | 42 | 1.40 |
| Gemini 3.1 Pro Preview | 2.00 | 12.00 | 4.50 | 1M | Feb 19, 2026 | 30 | 0.67 |
Prices retrieved October 4, 2026 from each vendor's own pricing documentation. Batch, cached-read and off-peak rates are excluded, as are the long-context adjustments described above. The index and cost-per-task columns are Artificial Analysis' Intelligence Index v4.3.2, read the same day, at each model's best published configuration, which is usually maximum effort. That scale scores configurations rather than models: Opus 5.5 is 58 at maximum effort and 54 at high. Composer 2.5 has no entry in either column because Artificial Analysis rates it as a coding agent instead.
Keep reading
Related posts
Three more worth reading, if this one landed
AI Watermarks Are Here. The Danger Is They're Not That Good.
Since August 2, 2026, Claude marks everything it writes. Most of the worry is about being caught. The real problem is that the mark cannot prove what people are about to use it to prove.
Best No-Code, Low-Code & AI Tools to Build Apps & Websites (2026)
The no-code category split in half. On one side, visual builders that still can't export your code. On the other, AI agents that write real software. Here's what's actually worth using in 2026.
Will AI Take Your Job? The Honest, Uncomfortable Answer
I make money helping businesses use AI. I also think it may be one of the most economically destructive technologies we have ever created. Both things can be true.